SSH drops when idle and ServerAliveInterval does not help
ClientAliveInterval 30 did not drop a single idle session
The session connects, ls prints instantly, you leave it idle for thirty seconds while you check something in another terminal. When you come back it is frozen, and the client says Connection reset by peer. You search, every result tells you to set ServerAliveInterval. You set it to 60 and the session still dies.
I tested that advice this afternoon on a lab machine: an Ubuntu 24.04.4 server running OpenSSH_9.6p1 and a client running OpenSSH_10.2p1. By the end of this you will know why ClientAliveInterval 30 does not disconnect idle sessions, why ServerAliveInterval 60 killed a session that no keepalive at all would have survived, and what the 79 in exit=255 after 79s means.
What the stock server ships with
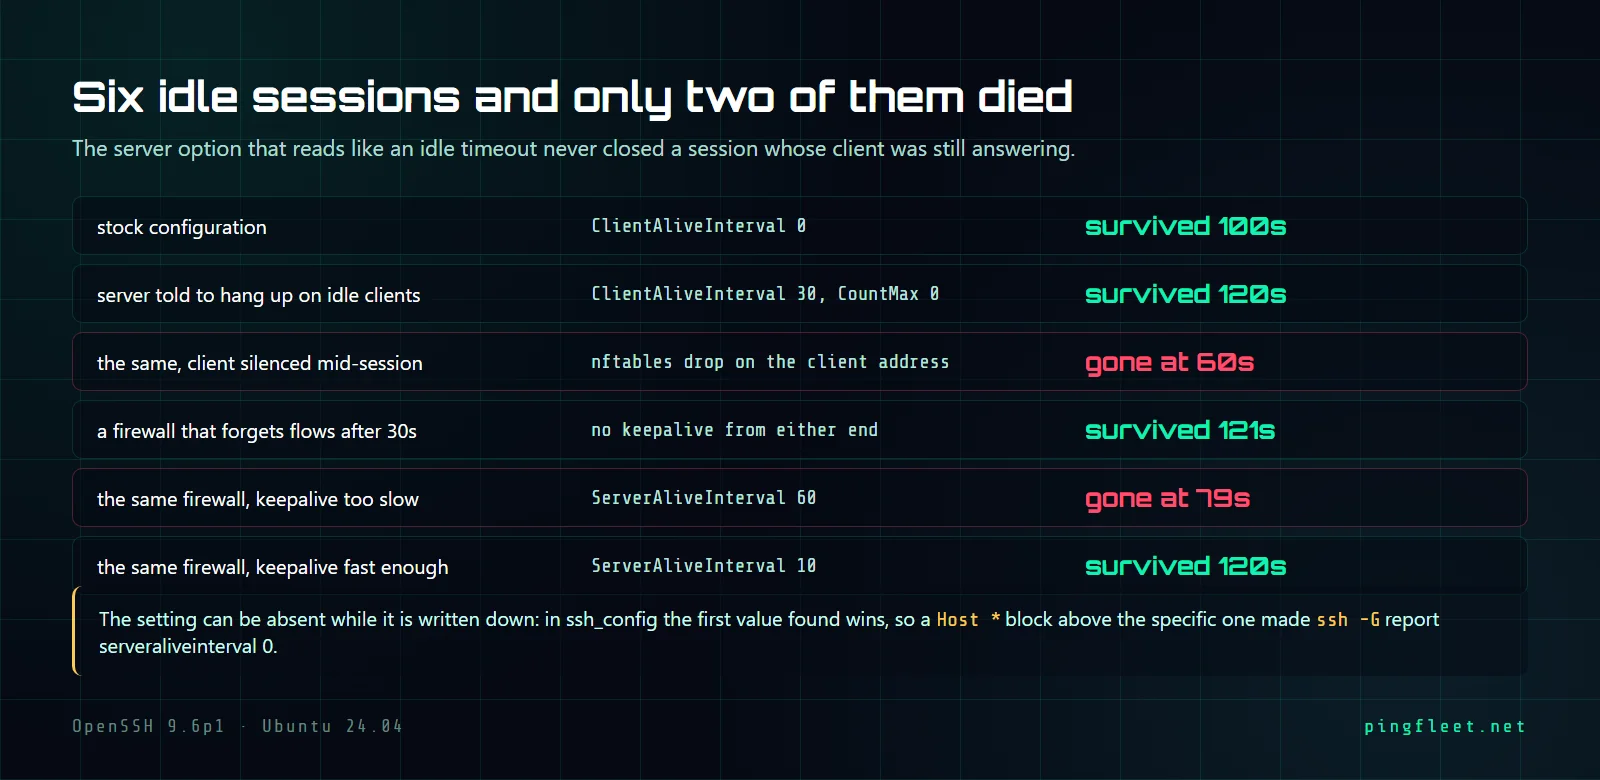
The default sshd_config on Ubuntu 24.04 has three relevant settings: ClientAliveInterval 0, ClientAliveCountMax 3, TCPKeepAlive yes. A session I left idle for 100 seconds on this stock configuration exited cleanly with code 0, and nothing tried to disconnect it.
Does ClientAliveInterval drop idle sessions?
I set ClientAliveInterval 30 and ClientAliveCountMax 0 on the server. That combination should mean: probe after 30 seconds of silence, tolerate zero missed responses, disconnect. The client had no ServerAliveInterval set.
The session survived 120 seconds and exited 0.
I added ServerAliveInterval 10 on the client side and ran the test again: exit 0 after 120 seconds. Then TCPKeepAlive yes alone, without ServerAliveInterval: exit 0 after 121 seconds. All 3 tests survived and the server disconnected none of them.
The explanation is in the sshd_config man page but it does not jump out at you. The ClientAliveInterval directive sends a message "through the encrypted channel," which means it uses SSH protocol-level messages as defined in RFC 4254, and the client answers those messages automatically whether or not ServerAliveInterval is configured. The ClientAliveCountMax counter increments only when the server receives no response at all. An idle client that is still reachable answers every probe, the counter stays at 0, and the session lives indefinitely.
The first value wins in ssh_config
I hit a config ordering bug before I reached the firewall test. In ssh_config, the first obtained value for each parameter wins regardless of specificity. I had a Host * block with ServerAliveInterval 0 placed above my specific host block that set it to 10, and ssh -G 192.168.3.138 confirmed the effective value was serveraliveinterval 0.
I assumed the more specific match would win regardless of position, the way firewall rule sets work. Swapping the two blocks so the specific host came first changed the output of ssh -G to serveraliveinterval 10. If your ServerAliveInterval seems ignored, run ssh -G <hostname> before debugging anything else.
A 30-second conntrack timeout produced three different results
To reproduce what a NAT gateway or cloud security group does when it forgets idle flows, I set nf_conntrack_tcp_timeout_established to 30 and disabled nf_conntrack_tcp_loose. The nftables chain drops anything conntrack classifies as ct state invalid:
table inet labct {
    chain input {
        type filter hook input priority mangle; policy accept;
        ct state invalid counter packets 1 bytes 40 drop
    }
}
After 30 seconds with no traffic, conntrack forgets the flow and the next packet is classified invalid and dropped. I ran 3 sessions against this with the server on its stock settings.
With no keepalive at all, the session survived 121 seconds and exited 0. With ServerAliveInterval 60, the session died at 79 seconds with exit 255 and the client printed Read from remote host 192.168.3.138: Connection reset by peer. With ServerAliveInterval 10, the session survived 120 seconds, exit 0. The drop rule's counter after the full run showed 47 packets totaling 3948 bytes dropped.
At the 60-second mark the client sends its first keepalive probe, but the conntrack entry expired 30 seconds earlier. The probe arrives as invalid, gets dropped, the client retransmits, those retransmits are also invalid, and TCP gives up at 79 seconds.
The 10-second result is the fix: a probe every 10 seconds is shorter than the 30-second timeout, so the entry gets refreshed before conntrack can forget it. The setting works only when its value is shorter than whatever in the path is forgetting the flow.
Why did the session with no keepalive survive?
This was the result I did not predict. Neither side had ServerAliveInterval or ClientAliveInterval set, and after the session went idle no traffic passed in either direction. The conntrack entry should have expired at 30 seconds and the next packet should have been dropped.
The key is who speaks first after the entry expires. With no keepalive the client sends nothing, so nothing from the client ever hits the ct state invalid drop rule. When the server eventually sends an outbound packet (sleep finishing, TCP housekeeping), that packet goes through OUTPUT, not INPUT, and it creates a fresh conntrack entry. Any reply from the client now matches the new entry. A forgetful device in the path kills the flow only if the client speaks first after the entry is gone.
I think most people who set ServerAliveInterval pick 60 or 120, which is long enough to miss the window of any device with a 30-second or 60-second timeout and short enough to guarantee the client breaks the silence first. Setting it to 60 against a 30-second timeout is worse than not setting it at all, because without it the client would have stayed quiet and the server's outbound traffic would have reopened the path.
What the server logged when a client actually went silent
To confirm what ClientAliveInterval is actually for, I set ClientAliveInterval 15 and ClientAliveCountMax 2 on the server, connected from 192.168.3.158, and 20 seconds into the session armed an nftables rule that silenced the client for 120 seconds. The server should disconnect after accumulating enough unanswered probes.
The client exited 255 at the 50-second mark with Connection reset by peer. The server's auth log showed the other half:
Sep 20 16:40:01 sshd[2296]: Accepted publickey for claude from 192.168.3.158 port 50393
Sep 20 16:41:01 sshd[2345]: Timeout, client not responding from user claude 192.168.3.158 port 50393
Session opened at 16:40:01, server gave up at 16:41:01, which is 60 seconds. The client was silenced at t=20, and ClientAliveInterval 15 times ClientAliveCountMax 2 gives 30 seconds of unanswered probes, but the probe clock had already been running before the client went quiet. The server let go at t=60, and the client reported Connection reset by peer at t=50. This is what the setting does. It detects clients that have genuinely stopped responding, not clients sitting idle with an open terminal.
Check the path, then check the config
When an SSH session dies idle, the first thing to verify is that your ServerAliveInterval is taking effect. Run ssh -G <hostname> and look at the serveraliveinterval line in the output. If the value is 0 or different from what you set, your ~/.ssh/config blocks are in the wrong order and Host * is winning.
If the value is correct and the session still drops, the cause is a stateful device in the path forgetting the flow. Set ServerAliveInterval to something shorter than that device's timeout. In my test, 10 worked against a 30-second conntrack timeout and 60 did not, and the session with no keepalive at all outlived both because the client never sent a packet.
Server-side session monitoring has a blind spot here: the client in my control test saw Connection reset by peer at t=50 and exited, but the server did not log Timeout, client not responding until 16:41:01, a full 10 seconds later. Any tooling that reads sshd session state during those 10 seconds would report a connected client that was already gone.