Monitoring
Cron job monitoring
The check runs in reverse: your job calls us, and silence is the incident.
Free plan with 20 monitors. No card.
What it checks
Cron job monitoring
A nightly backup that stops running fails silently for months. Nothing is down, no page is red, and the discovery happens on the day the backup is needed.
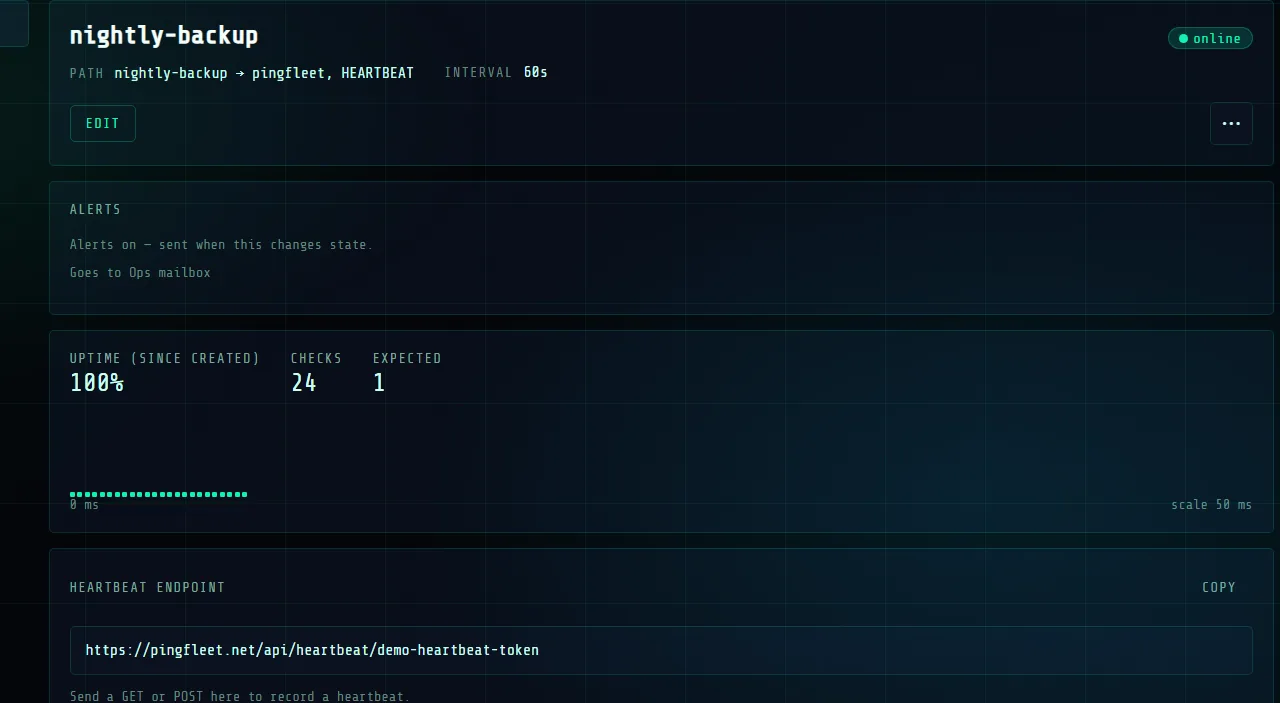
One line at the end of the job: curl -fsS https://pingfleet.net/heartbeat/<token>. Because it only runs on success, a job that dies halfway reports nothing, which is the point.
- A URL your job requests when it finishes successfully.
- A window you set. No call inside the window opens an incident.
- An optional payload (records processed, bytes written) stored with the beat.
It comes with the rest of the platform
Every monitor type shares the same alerting, the same status pages and the same map: escalation with on-call hours, a public status page, checks from independent networks, and agents for anything the internet cannot reach.
Questions
- What if the job runs but fails?
- Call the URL only on success: put it after the last step, and let a non-zero exit skip it. A job that failed and reported anyway is worse than no monitoring.
- Does it work from a machine with no inbound access?
- Yes. The call is outbound from your machine to us.